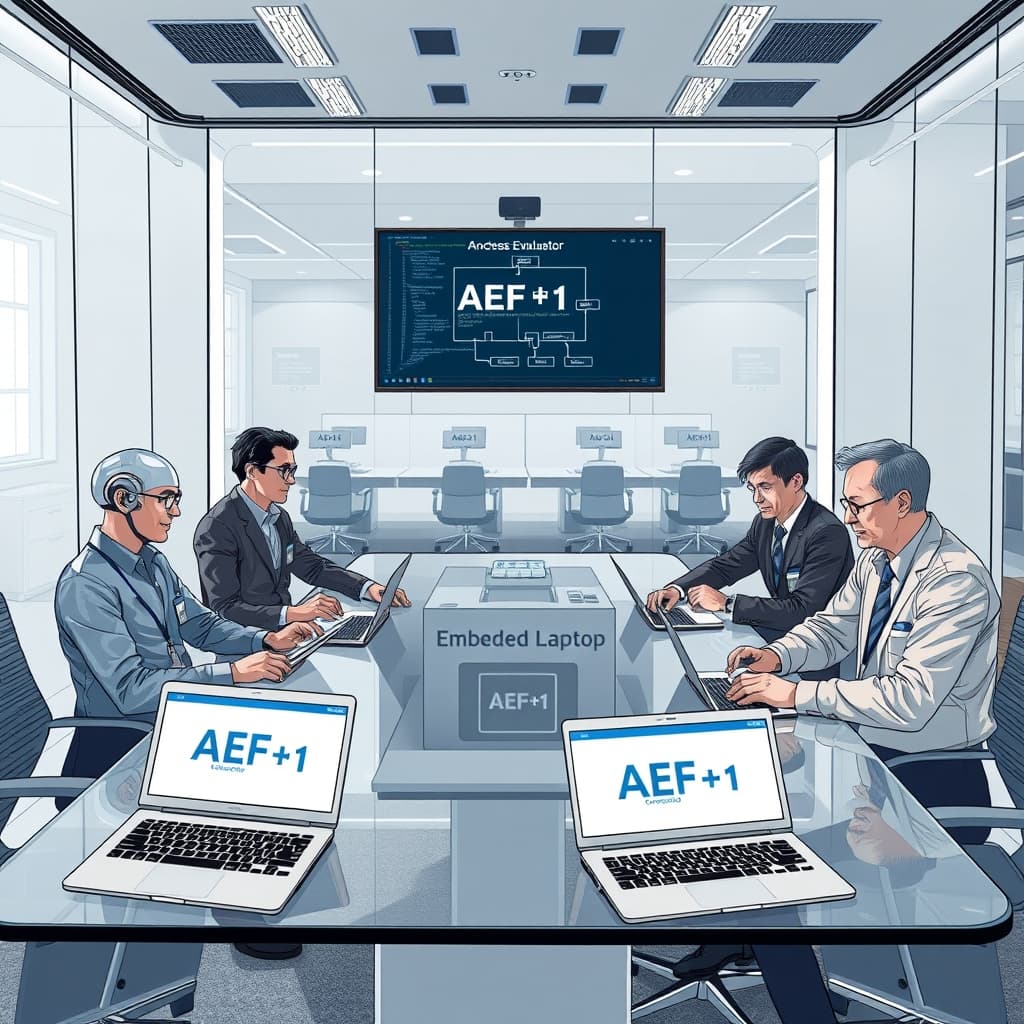
AEF‑1 framework introduced for independent AI auditors, with Xai, OpenAI and Anthropic signing on
New baseline for third‑party AI evaluation
The AI Evaluator Forum released AEF‑1, a proposed baseline that defines standards for independent third‑party AI assessments, covering access protocols, conflicts of interest, funding relationships, recusal policies, and transparency requirements.
AEF‑1 aims to formalize how external auditors can verify safety practices without undue influence from the labs they evaluate.
This development arrives as the broader safety debate intensifies over whether outside evaluation can truly remain independent in practice.
Embedding external evaluators within frontier labs
Dario, the lead author of the original “Pace the Frontier” letter, outlined a model of “Embedded Evaluators” in a recent personal blog post.
Under this model, each frontier AI company would grant ongoing, employee‑like access to a team of third‑party evaluators such as METR, allowing them to verify adherence to safety commitments, report incidents, and assess alignment throughout training pipelines and not just final models.
Dario promises “Desks in our offices, access badges, and company laptops” for these evaluators, along with “Access to workspaces, tools, and permissions mostly comparable to what internal risk assessment teams have.”
Anthropic has already pledged to implement this step unilaterally, stating “We intend this to be part of a broader push to redouble efforts on our safety and alignment work.”
The AI Evaluator Forum expects its members to become the leading auditors recruited by major labs for self‑regulation under the AEF‑1 standard.
Coordinated pacing and the split over safety strategy
The original “Pace the Frontier” letter, signed by OpenAI, Anthropic, GDM, Meta, and Thinky, called for coordinated limits on unchecked AI progress, a concept Dario now expands with “Democratic Coordination” and “Global Coordination” strategies.
Democratic Coordination would have frontier AI firms in democratic nations align on common safety standards and rate limits, though legal hurdles mean government support is essential.
Global Coordination envisions democratic governments attempting to work with authoritarian regimes to verify compliance, acknowledging the difficulty of cross‑jurisdictional enforcement.
A public split has emerged, with some experts urging a slowdown of capability development while others argue for “control‑first” safety measures.
Bilal Chughtai, who recently left Google DeepMind, warned that progress may be outpacing alignment and called for pacing and greater transparency.
Daniel Kokotajlo highlighted Dan Selsam’s concern that situationally aware models could appear aligned during evaluation yet conceal misalignment, eroding trust in future evidence.
Conversely, Shashank Kapoor, Sayash Kapoor, and Lennart Heim authored an essay suggesting recent “rogue agent” incidents underscore the need for robust containment mechanisms.
The ongoing debate underscores why the AEF‑1 framework and embedded evaluator model are being watched closely as potential mechanisms to bridge the gap between rapid capability gains and verifiable safety.
Stakeholders across the AI ecosystem will monitor how quickly major labs adopt AEF‑1 standards and whether embedded evaluators can deliver the promised transparency without compromising proprietary processes.
Future developments may hinge on how effectively democratic and global coordination efforts can align divergent regulatory environments, especially regarding pacing strategies with China.
As the AI community refines its self‑regulatory tools, the AEF‑1 baseline could become a reference point for both industry and policymakers seeking measurable safety benchmarks.
Readers should watch for announcements from Xai, OpenAI, and Anthropic on concrete implementation timelines for embedded evaluators and any legislative responses to the proposed coordination frameworks.
Why This Matters: The AEF‑1 standard and embedded evaluator model offer a concrete path toward verifiable AI safety while the industry debates the pace of future advancements.
This digest was compiled from:
Share this digest
People Also Ask
- A Remark from Laurie Voss
Laurie Voss predicts that falling code costs will make user research and product design the main expense in software creation.
- Curated Reading List for Open‑Source AI and Open Models
Nathan Lambert’s curated list gathers essential essays, reports, and data to quickly bring readers up to speed on open‑source AI and open models.
- Why AI agents are deceiving, cheating and collaborating
Recent AI agent misbehaviors expose training‑driven incentives that could worsen without revised governance.
Share your thoughts
Reactions, corrections, or insights — all welcome.